
Partner Communication During a Disaster
"Has anyone told the bank?" Nobody has told the bank. It is a quarter to three, the storage died twenty-five minutes ago, and every person who could have made the call is looking at a console. Meanwhile forty other teams are watching their own jobs fail against your server. Some will retry quietly for hours. Some will open a ticket with their own help desk, who will call yours. Some will assume the worst and resend everything they have sent this week, the moment the service reappears. And one — the bank, with its six o'clock cutoff — will make a decision about your payroll file based on whatever it has heard from you. So far, that is nothing.
Partner communication is the half of disaster recovery that runs on the phone and in the mailbox rather than on the console. It has its own procedures, templates, and traps. This article covers what to prepare before a disaster, what to say in the first notice and what not to promise. It covers how often to update and the changes partners may need to make on their side. It covers the catch-up plan for files that were lost or never arrived, and how to stop both sides from resending the same files. It covers the all-clear that ends it. This article is part of our Disaster Recovery for Transfer Workflows series. It is the communications track that runs alongside The Transfer Disaster Recovery Runbook. Somebody has to be the person who is not looking at the console. This article is for them.
Why Partners Must Hear From You First
A transfer partner is any organization whose systems exchange files with yours on a schedule. Examples are the bank that takes your payroll file, the insurer that sends claims, and the agency that collects assets. Each has automation that expects your service to be there, and each has its own deadlines. A cutoff is the time by which a file must arrive to be processed that day. When your service disappears, their automation does not know why, and their people fill the silence with guesses. Silence is a message too, and never the one you meant.
Silence costs you three ways. Partners retry, which is harmless, or resend everything, which creates the duplicate problem covered later. Partners escalate, which means your team is answering calls instead of restoring. And partners make deadline decisions without the one fact that would change them: whether your file is coming today. Hearing from you first — before their monitoring or their help desk does — turns forty anxious parties into forty parties waiting for your next update. That is worth a person's full attention, which is why the runbook gives the communicator role to someone who is not touching the restore. I have been the person touching the restore, and I did not answer the phone.
Before the Disaster: The Partner Contact Sheet
Nothing in this article works without a contact sheet that exists before the disaster and is stored somewhere the disaster cannot reach. It holds, per partner and flow, the people to call (the same names flow ownership and contacts asks you to record). It holds their deadlines and how their side behaves when yours is gone. Most of it is gathered at onboarding — our partner onboarding runbook has the questions. The contact sheet is refreshed once a year, a habit keeping partner documentation current makes routine. The shape:
PARTNER CONTACT SHEET — transfer platform    (printed copy with the DR runbook; also offsite)

Ref   Partner / flow                 Technical contact        Business contact        Escalation
B-01  First Example Bank / payroll   file desk  +1 555 0101   treasury  +1 555 0102   duty manager +1 555 0100
      Direction: we push, SFTP       Cutoff: 18:00 our time, business days
      Their side when we are down:   job retries every 30 min until 19:00, then flags "missing"
      They pin: our host key + IP allowlist      Notify via: email + phone for anything affecting cutoff
      Late-file procedure:           call file desk before 17:30; late window to 20:00 by arrangement

B-02  Acme Mutual / claims inbound   integration +1 555 0201  claims ops +1 555 0202  +1 555 0200
      Direction: they push, SFTP     Their sending window: 06:00-20:00, roughly hourly
      Their side when we are down:   their job queues files and retries; NO automatic resend of delivered files
      Resend on request only — send them the list.     Notify via: email to integration list

B-03  Example Creative / assets      studio IT  +1 555 0301   account mgr +1 555 0302  —
      Direction: they pull, HTTPS    Weekly, Mondays; low priority; email only

Status channel for all partners: status mailbox transfer-status@example.com; phone bridge on request
Two lines earn their place on a bad day. "Their side when we are down" tells you which partners will resend on their own and which will wait. That is the difference between a partner you must ask and a partner you must stop. "They pin" tells you which partners need to act if recovery changes your address or your keys. Neither is knowable during a disaster; both are a five-minute conversation during onboarding. Five minutes at onboarding, or a very long afternoon later.
Northgate Retail found out what the sheet was worth on an ordinary Tuesday. A storage controller failed at ten past nine, and the recovery lead declared at half past. The communicator opened the printed sheet, took the template, and filled in the three flows affected. The first notice was out to eleven partners by nine thirty-four. Four minutes. The sheet had been refreshed the previous month, so every address and phone number worked the first time. One partner replied within ten minutes to say they had paused their job and would wait for the update. Nobody on the restore team took a single call that morning. The refresh had taken an hour, a month earlier, and had felt like a chore at the time.
The Initial Notice
The first notice goes out within the hour of declaring. It goes out even though you know almost nothing, because "we know and we are on it" is the message. It is short, factual, and ends with a time for the next update. The template below has the payroll bank's version filled in:
Subject: [Example Corp] File transfer service disruption — payroll flow affected — update at 16:00

To: First Example Bank file desk

Our file transfer service (sftp.example.com) is unavailable following a storage failure at
approximately 14:20 our time. We have declared a recovery and are restoring the service.

What this means for you:
- Our scheduled payroll file (PAYROLL_YYYYMMDD.txt, normally delivered by 17:30) may be late.
- Your connections to us will fail until further notice. Please do not resend files or
  change your configuration unless we ask you to.

What we are doing: restoring the service from backups at our recovery site. We will confirm
before 16:00 whether today's payroll file will meet the 18:00 cutoff, or arrange a late
delivery with you by phone.

Next update: 16:00, or sooner if anything changes.
Contact for this incident: [communicator name], [phone], transfer-status@example.com
Reference: INC-DR-[number]
What to promise: that you will update at a stated time, what flows are affected, and what the partner should not do yet. In the first notice, never promise a restoration time you have not measured or a root cause you have not confirmed. Never promise that "no data has been lost" before the RPO gap has been established. A partner who is told "back by four" and then not back by four stops believing the next update. A partner who is told "next update at four" and gets one at four keeps believing. I have sent the first kind of message, once, and regretted it by ten past four. The gap between those two sentences is most of the craft.
Remember: promise the next update, not the outcome. Every notice ends with a time you will speak again, and you keep it even when the only news is that there is no news.
The Update Cadence
After the initial notice, updates go out at a fixed interval — every two hours works for most flows. They also go out whenever a fact changes that a partner can act on. The "no change" update matters as much as the others: it is the evidence that the incident is being managed. Each update repeats the reference number and states the current runbook phase in plain words ("server rebuilt; verifying keys and accounts"). It restates what partners should and should not do, and names the next update time. The timeline below shows the whole communications track against the restore.
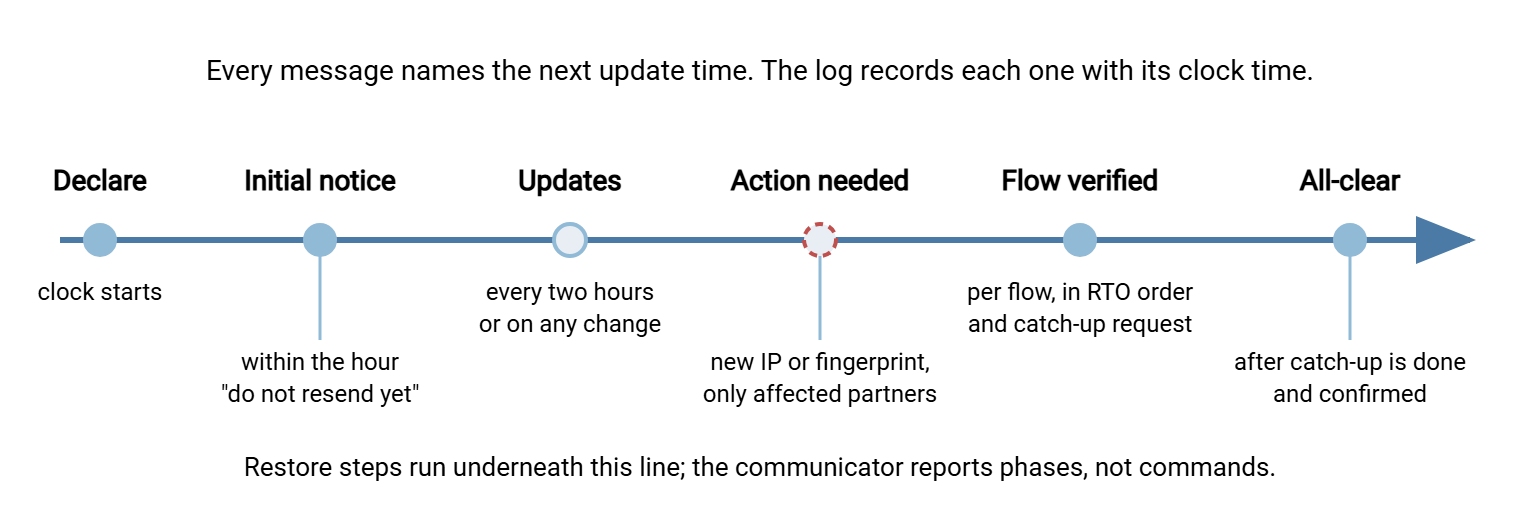
Send the same update to internal stakeholders — the payroll manager, the claims team, the help desk — with one extra line on what to tell callers. A help desk that knows the reference number and the next update time absorbs most of the inbound noise that would otherwise reach the restore team. It is the cheapest firewall you will ever deploy.
Changes Partners Must Act On
Most of the time the restored service looks identical to partners and they need to do nothing. Three recovery outcomes break that, and each needs its own targeted notice. Send it only to the partners it affects, and mark it clearly as requiring action:
- A new IP address. If the recovery site's address differs and a partner allowlists you, their firewall must change before their flow works. Tell them at the network step of the runbook, not at the end, because their change process may be the slowest thing in the whole recovery. Include both the old and new addresses and whether the old one will return.
- A new host key or certificate. Only in the compromise case, where keys were rotated rather than restored. Partners' automation will refuse the new key until they update their records, so send the new fingerprint — and send it through a channel they can trust. An email that says "our fingerprint has changed, please accept the new one" is exactly what an attacker would send. Confirm the fingerprint by phone with the technical contact, or through the partner portal they already trust. Our host keys and known_hosts article explains what partners will see and how they update it.
- A changed account or path. Rare in a faithful restore, but if the recovery changed a home folder or account name, say so explicitly with the old and new values side by side.
Keep these notices separate from the status updates. A partner who receives ten updates and one "action needed" notice buried among them will miss it. The mechanics of walking partners through a change on their side are the same as in a planned migration, covered in coordinating partners through your migration.
The Catch-Up Plan for Missed Files
Recovery restores the service. It does not restore the files that were lost between the last backup and the disaster, or the ones that never arrived while the service was down. That is the catch-up, and it needs partners. Work the example: the storage failed at twenty past two. The runbook's four-hour RTO put the service back, verified, at ten past six. The newest data backup was from one in the morning.
Outbound payroll. The bank's cutoff was six. The decision point in the runbook fired at half past three — "will the tightest-RTO flow miss its cutoff?" — and the answer was probably. So the communicator called the file desk before half past five (the late-file procedure on the contact sheet) and arranged the late window. The file was delivered by hand from the upstream payroll system at a quarter to seven. The catch-up for an outbound flow is usually this simple. The source system still has the file, and the question is only whether the partner can take it late. Our cutoff times and deadlines article explains why the phone call must come before the cutoff, not after.
Inbound claims. The insurer sent files hourly all day. Everything they sent between one in the morning and twenty past two arrived and was then lost with the storage. Everything after twenty past two was never received. The partner holds all of it, but they need to be told exactly what to resend. The activity log is where that list comes from. A server such as Sysax Multi Server records each login and transfer in its activity log. If that log was shipped off the box continuously it survives the disaster. The catch-up request looks like this:
Subject: [Example Corp] INC-DR-[number] — claims flow restored — please resend 37 files

Our service is restored and verified as of 18:10. For the claims flow we need two groups resent:

Group A — received by us but lost with the storage (01:00 to 14:20 today): 37 files.
          List attached (name, size, time received) from our activity log.
Group B — anything your side attempted after 14:20 that did not complete.
          Your job log will show these; please include the list with the resend.

Please resend into your usual inbox folder. Do not resend anything received before 01:00;
those files are intact. If you are unsure whether a file is in Group A, send it — we will
reconcile by name and hash and tell you what we discarded.

Please confirm when the resend is complete. We will confirm receipt file by file.
The mechanics of replaying a missed batch in order, and of what downstream systems need to know, are in catch-up after failures. The DR-specific part is that the list of what to resend comes from your log, not from the partner's memory. The request also says explicitly what not to resend.
Avoiding Duplicates When Both Sides Resend
The worst catch-up outcome is not a missing file; it is a file processed twice — a claim paid twice, a payroll run twice. Duplicates arise during recovery because both sides are trying to help. The partner resends "to be safe," your restored job re-pushes what is in the outbox, and a well-meaning operator re-runs a batch. Three rules prevent it.
One side resends; the other side asks. Agree this at onboarding and restate it in the initial notice ("please do not resend unless we ask"). For inbound flows, you ask and the partner resends. For outbound flows, the partner asks and you resend. Nobody resends unsolicited.
Reconcile before processing. Every resent file lands in the inbox like any other. Before anything downstream touches it, it is reconciled against what you already have — by name, size, and hash. A hash is a short fingerprint of a file's contents; two files with the same hash are the same file. The reconciliation for four of the claims files:
| File (from partner's resend list) | In our log? | In restored inbox / archive? | Action |
|---|---|---|---|
| CLAIMS_0930_0412.csv | Yes, 09:31 | No (lost) | Accept resend; process |
| CLAIMS_0030_0409.csv | Yes, 00:32 | Yes, hash matches | Duplicate; move to quarantine, tell partner |
| CLAIMS_1500_0415.csv | No | No | Never arrived (Group B); process |
| CLAIMS_1100_0413.csv | Yes, 11:02 | Yes, hash differs | Hold; ask partner which version is correct |
The techniques for doing this at scale — sequence numbers in file names, a register of processed hashes, a quarantine folder for anything already seen — are in detecting duplicates. During recovery, run them by hand if you must, but run them.
Make downstream safe to re-run. The strongest protection is a consuming system that ignores a file it has already processed. It is idempotent, in the jargon, meaning that doing the same thing twice has the same effect as doing it once. Not every downstream system is, and a disaster is not the moment to find out which. The article safe reprocessing patterns is the reading for making them so. The contact sheet should note, per flow, whether the consumer is safe to re-feed. "Probably" is not one of the permitted values for that column.
The All-Clear and the Review
The all-clear is sent once, when three things are true. Every flow on the scope worksheet is verified. The catch-up for each is complete and confirmed by the partner. Normal monitoring has been watching the service long enough to trust it — typically one full cycle of every scheduled job. Sending it earlier means sending it twice, and the second one is not believed.
Subject: [Example Corp] INC-DR-[number] — RESOLVED — file transfer service fully restored

The file transfer service (sftp.example.com) has been fully restored and all scheduled
flows have completed at least one normal cycle.

For your flow: [payroll delivered 18:45 under the late window agreed by phone / 37 claims
files resent and reconciled; 1 duplicate discarded, 1 version confirmed with your team].
No action is required on your side. [Our address and host key are unchanged.]

We will hold a short review of this incident and will share a summary, including anything
that would make the next recovery smoother for both sides, within two weeks.

Thank you for your patience. Reference INC-DR-[number] is now closed.
The review is where partners become part of the plan. Ask each affected partner three things: when did they first notice, what did their automation do, and what would they have wanted to hear sooner? Their answers go into the same findings log the drills use, alongside the technical ones. The fixes flow back into the contact sheet and the templates. A partner who says "we resent everything at three because we had heard nothing" has just told you the initial notice was late. A partner who says "our job flagged the missing file at seven and nobody knew why" has told you which flow needs a per-flow notice. The format for running that conversation without blame is in running a blameless postmortem, and the technical half of it feeds Restore Drills: Proving the Plan Works.
Bringing It Together
Partners are the outermost ring of the DR scope, and the only ring you cannot restore from a backup. What you can do is prepare the contact sheet before the disaster and send the first notice within the hour. Promise update times rather than outcomes, and keep the cadence. Tell the affected partners exactly what to change and confirm fingerprints through a channel they trust. Drive the catch-up from your own logs with an explicit "do not resend" list. Reconcile every resent file before anything downstream sees it, and send the all-clear once. Then ask the partners what they saw, and put the answers back into the plan. The plan, unlike the disaster, will hold still while you do.
The other five articles in this series cover the technical half. They cover what the scope includes in Disaster Recovery Scope: More Than the Server. They cover the runbook the communicator works alongside in The Transfer Disaster Recovery Runbook. For the ongoing relationship the incident tests, SLAs and expectations for partner exchange is the companion read.
Frequently Asked Questions
How soon after a disaster should partners be told?
What should we avoid promising in a partner notice?
How do we tell partners which files to resend?
How do we stop duplicates when partners resend?
When is it safe to send the all-clear?
From the Sysax team: we build secure file transfer software for Windows. Sysax Multi Server is an FTP, FTPS, SFTP, and HTTPS server. Sysax FTP Automation handles scheduled, scripted transfers. Free trials are on the download page.